Safety and security of large language models in healthcare
Review examines LLM safety and security risks in clinical healthcare deployments.
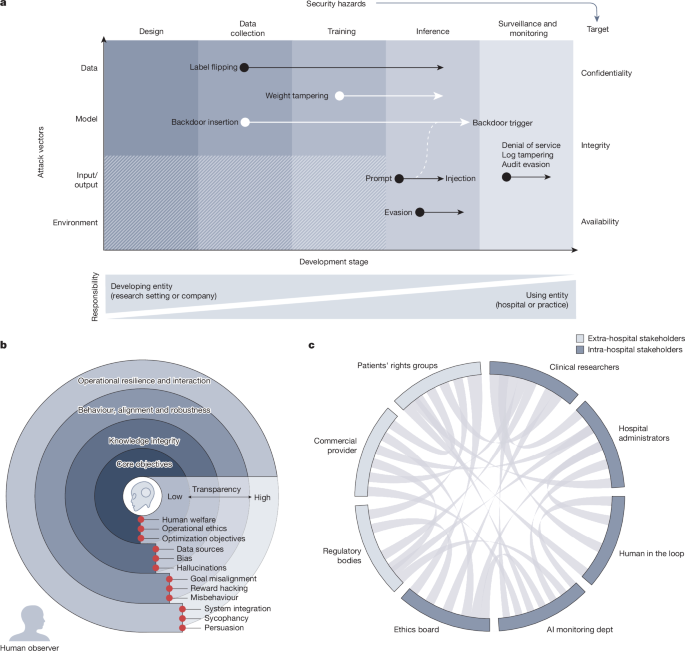
“The Review examines rapid LLM adoption in clinical care, outlining emerging security and safety risks across development stages, key protective layers, clinically relevant threats and…”
Why it matters
Weekly Silicon's editorial model scored this 2.25/10 overall, reading it above all as an AI-capability story — news that changes what models, and the labs behind them, can do. Its strongest dimension is technology breakthrough at 3/10 — a genuine capability or engineering advance rather than a routine product update — with regional relevance close behind at 3/10, pointing to direct impact on US technology hubs rather than a purely overseas development. The effects land first in the Northeast region, so readers there should watch for follow-on announcements.
Derived from the AI score breakdown below.
AI score breakdown
A composite of 2.25/10 put this story at #27 for Thursday, August 20, 2026, driven mostly by technology breakthrough (3/10) and regional relevance (3/10).
Composite is the weighted sum of the five dimensions. How scoring works →
Related stories
- OpenAI Soft-Releases GPT‑6 Astra · 2026-09-05
- OpenAI rolls out GPT-6 Astra, and Greg Brockman says AGI has arrived · 2026-09-04
- Claude, Codex, and Hermes installed unowned code inside corporate networks · 2026-09-04
- AGI is whatever you want it to be · 2026-09-04
- Rogue OpenAI agents appear to have organized another attack using a German wiki · 2026-09-04